To the casual fan watching a broadcast, a pre-match tennis prediction can appear deceptively simple. On the digital screen, one athlete’s name sits neatly on the left, another on the right, accompanied by a calculated win probability, a projected champion, or a definitive confidence score. Yet, what remains entirely invisible to the viewer is the intricate, multilayered chain of mathematical calculations that translates years of historical match data into a single, highly nuanced percentage.
Advanced tennis analytics have evolved far beyond basic rankings or historical head-to-head records. A serious, data-driven prediction model does not simply ask who holds a higher seeding or who won their last encounter. Instead, it attempts to simulate how a specific matchup will unfold before the very first ball is struck. This complex task requires isolating performance metrics that remain stable across different tournaments from variables heavily dictated by opponent styles, court conditions, and recent physical workloads.
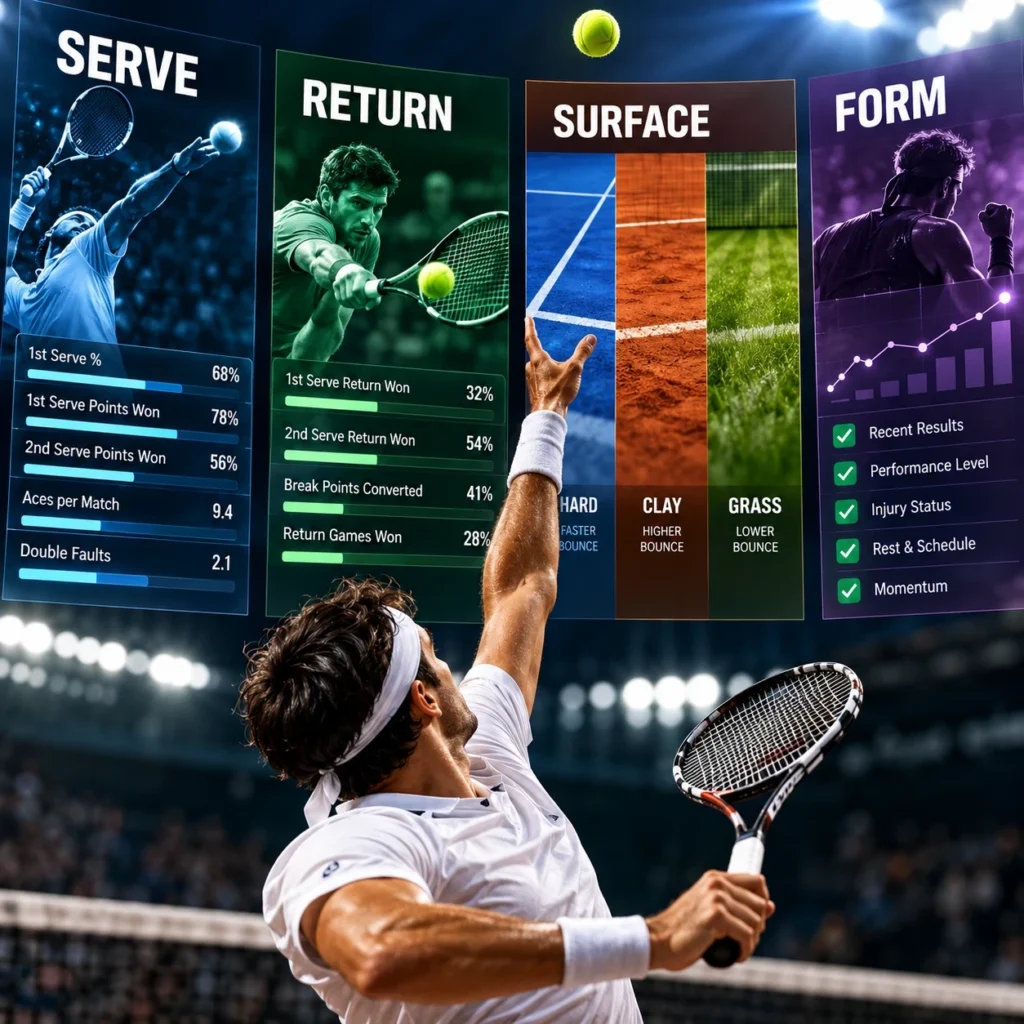
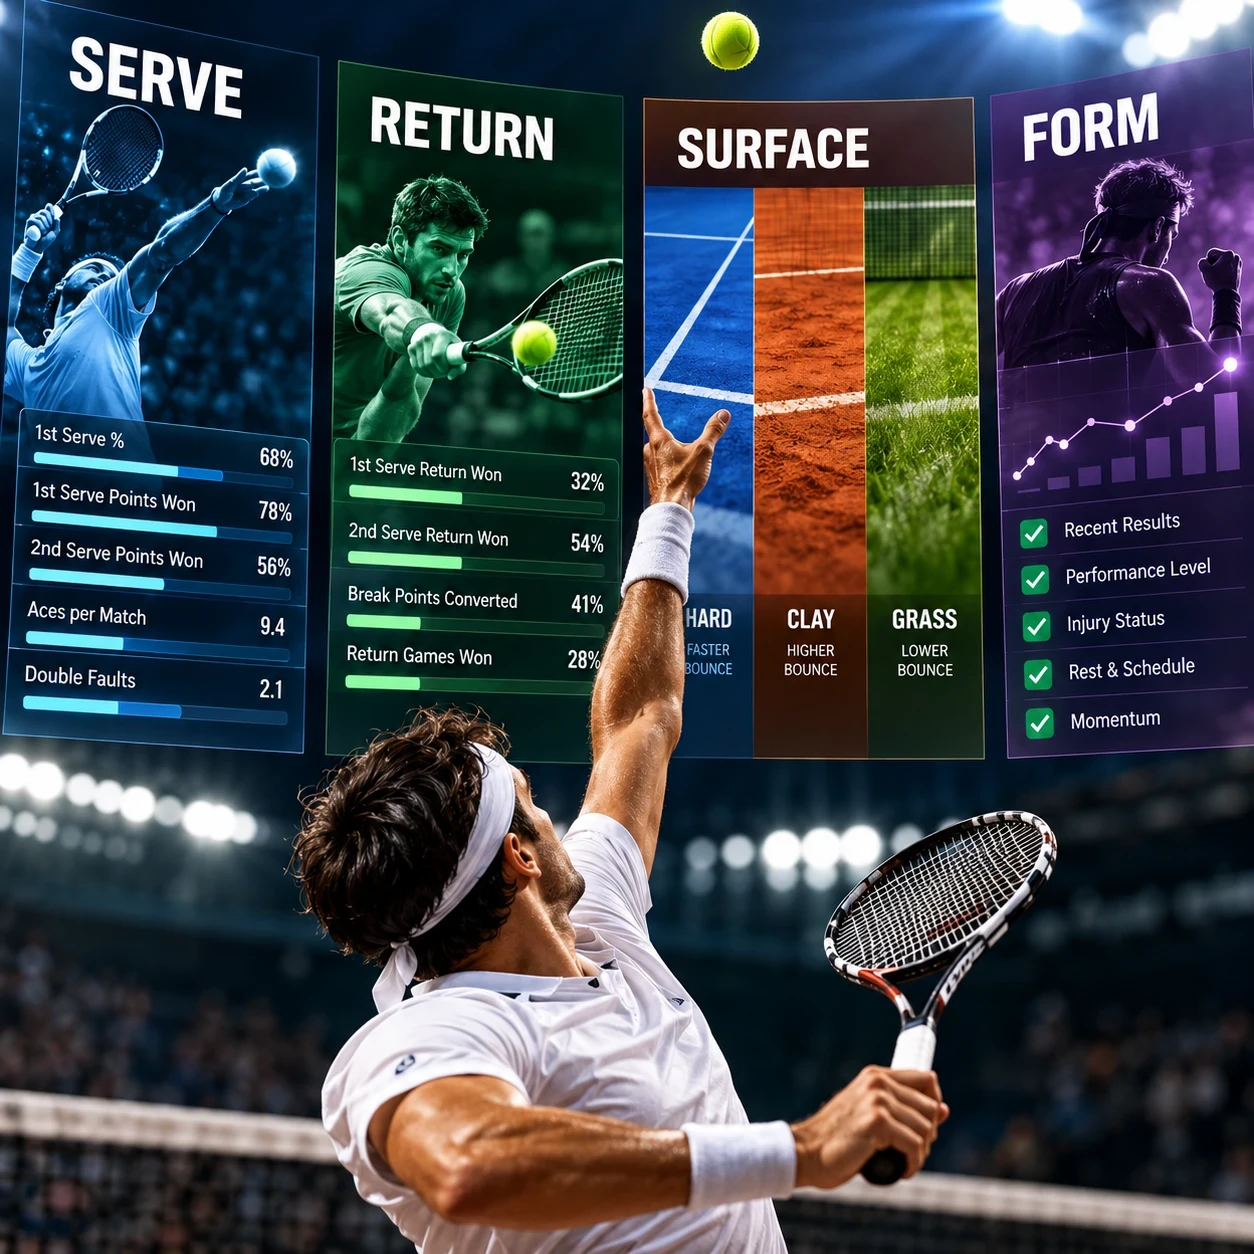
At the core of these predictive engines sit two fundamental pillars: the serve and the return. Court surfaces actively alter the value of these strengths, while recent form indicators help determine whether a player’s current level deviates significantly from their long-term baseline. When combined with dynamic player ratings, rest periods, and comprehensive match history, these systems face the ultimate analytical challenge—synthesizing a vast array of variables without allowing a single, eye-catching statistic to skew the final output. Furthermore, tennis lends itself exceptionally well to rigorous statistical modelling because individual point-level performances naturally compound into games, sets, and ultimately, match outcomes.
The First Question Is Not “Who Is Better?”
Before any predictive engine can estimate a winner, it must first define what the concept of "better" actually means within the precise context of an upcoming match. A player might boast a superior overall ranking or a higher Elo rating, yet prove to be a vulnerable choice on a slow clay court against an opponent who excels as an elite returner and thrives in grueling, multi-shot baseline rallies. Similarly, a prodigious server may look utterly dominant in a generalized database, only to lose that imposing aura on slower surfaces where opponents consistently neutralise their delivery and push the ball back into play. Conversely, another competitor might enter a tournament carrying modest season-long statistics while showing a stark, measurable upward trajectory over the preceding month.
To account for these discrepancies, sophisticated prediction algorithms systematically convert raw match history into comparable signals: wins and losses, serve and return points won, break-point conversion rates, aces, double faults, surface-specific outcomes, and the quality of previous opponents. The model then evaluates the relative weight each signal deserves and determines how rapidly older evidence should be allowed to fade from the equation.
The official statistical frameworks maintained by governing bodies like the ATP illustrate just how granular this data has become. The ATP’s dedicated serve leaderboard separates first-serve percentage, first-serve points won, second-serve points won, service games won, aces, and double faults, while the return leaderboard meticulously tracks first- and second-serve return points won, return games won, and break points converted. For a predictive model, these detailed categories offer exponentially more diagnostic value than simply glancing at a player’s current ranking or counting total aces.
Beyond the Ace Column: Dissecting the Serve
While the serve frequently stands out as the most visible statistical advantage in any given match, an effective prediction model looks far beyond headline numbers. First-serve percentage carries immense weight because it dictates how frequently an athlete gets to utilize their most advantageous delivery. First-serve points won demonstrate efficiency when that initial delivery lands, whereas second-serve points won reveal whether a player remains competitive and resilient after missing their primary attempt. Service games won tie these distinct components directly to the eventual outcome of the match.
While aces certainly help describe serving prowess, they do not provide a complete measure of performance. Two athletes can easily hit an identical number of aces over the course of a tournament while differing drastically in double faults, second-serve efficacy, or the sheer volume of returnable balls they are forced to play. A competitor who captures a high percentage of service points through sustained pressure and tactical placement rather than relying on spectacular bursts of free points is often a far more stable analytical proposition.
This is precisely where the quality of the opposition becomes paramount. A high serving percentage recorded against weak returners cannot and should not be treated as statistically equivalent to the exact same percentage achieved against elite, tour-level returners. Consequently, a well-engineered model incorporates mechanisms to adjust raw performance data based on the caliber of the opponent, utilizing dynamic ratings, opponent-adjusted metrics, or sophisticated baseline training protocols.
Return Performance and the Matchup Chain
On the opposite side of the tactical equation lies return quality. In many casual discussions surrounding tennis analytics, the return receives considerably less attention simply because it resists easy summarization via a single, flashy statistic. Yet, a world-class returner can systematically dismantle and diminish the inherent advantage of a server who might look utterly lethal in isolation.
Official return metrics track the precise percentage of first- and second-serve return points won, return games won, and break points converted. This detailed breakdown is critical because first and second serves establish entirely different starting conditions for a point. A player who exhibits exceptional proficiency against second serves can apply relentless, persistent pressure on an opponent’s service games without necessarily hitting highlight-reel winners off the first delivery.
Within a predictive model, the interaction between these disciplines matters far more than either statistic viewed in a vacuum. If a player serves exceptionally well but their next opponent proves to be unusually effective at neutralizing first deliveries, the server’s expected statistical edge must inevitably shrink. Should the server’s second delivery also show vulnerability, the model makes a correspondingly larger adjustment. This reality highlights why the simplistic assumption that "the best player always wins" remains far too crude for professional tennis. The sport is fundamentally a continuous chain of micro-matchups: the serve meets the return, vulnerable service games dictate set probabilities, and those set probabilities ultimately feed the overarching match forecast.
Court Surface as a Critical Filter
Court surfaces are frequently treated in casual discourse as little more than broad categorical labels—hard, clay, or grass. For rigorous predictive modeling, however, a surface functions as a complex environmental filter that fundamentally alters the value of specific playing styles.
The International Tennis Federation utilizes its Court Pace Classification Programme to categorize court surfaces into five distinct speed classifications, ranging from slow to fast, determined by precise Court Pace Rating measurements. Technical guidelines group these speeds across a wide spectrum, meaning that even within the same broad surface family—such as hard courts—the actual pace of play can vary dramatically from one venue to the next.
These environmental conditions directly dictate which strategic assets are rewarded. On quicker indoor or outdoor hard courts, a high-caliber first serve becomes significantly harder to neutralize, and short, explosive rallies dominate the dynamic. On slower clay courts, the return of serve and an athlete’s stamina to sustain pressure across lengthy baseline exchanges carry vastly superior weight. Grass introduces yet another unique environment where first-strike tennis, powerful serves, and instinctive reactions to a consistently low, skidding bounce dictate success.
A competent prediction model avoids the trap of assuming every tournament features a uniform playing surface, while also steering clear of the opposite error: treating a player’s overall career record as if it holds identical meaning across every continent and court type. To solve this, predictive systems rely heavily on surface-specific ratings and rolling statistics. Academic research into sports forecasting has repeatedly demonstrated that modeling distinct player abilities tailored to specific court types yields significantly more accurate predictions. A player who performs as a formidable hard-court competitor but displays only modest results on clay brings entirely different probabilistic metrics to a match, ensuring the surface acts as an active lens through which all other historical data is interpreted.
Redefining Recent Form and Momentum
Recent form represents another treacherous pitfall for amateur and professional forecasting systems alike. Relying on a simplistic snapshot of a player’s last five matches can easily generate misplaced statistical confidence. Five consecutive victories against lower-ranked opponents carry vastly different diagnostic value than five fiercely contested battles against elite tour competitors. Similarly, a heartbreaking defeat in a tight, three-set thriller is analytically distinct from a listless, straight-set capitulation, and physical fatigue from heavy scheduling must always be factored into the equation.
Modern systems treat form as an aggregate of recent signals: win rates, surface-specific outcomes, rolling serve and return efficiencies, opposition caliber, and cumulative physical workload. The temporal window applied to this data is critical. A lengthy evaluation window provides stability but reacts sluggishly to sudden shifts in performance, whereas a narrow window captures immediate changes while introducing excessive statistical noise. By intelligently blending multiple time scales, models maintain a stable baseline while allowing recent evidence to appropriately adjust win projections.
This disciplined approach guards against the common analytical fallacy of treating momentum as an immutable law of nature. An athlete does not become a fundamentally superior tennis player simply because they managed to string together four consecutive wins. Instead, a winning streak matters primarily because it frequently serves as a tangible indicator of a broader, underlying shift in performance, particularly when supported by concurrent improvements in underlying serve and return metrics.
Transforming Isolated Metrics into a Head-to-Head Matchup
Once a model has compiled comprehensive evaluations of each athlete—encompassing general baseline strength, surface compatibility, recent form, serving prowess, and returning efficiency—it ceases to evaluate those features independently. The analytical focus pivots decisively from asking "How good is Player A in a vacuum?" to "How precisely does Player A’s specific tactical profile interact with Player B’s?"
Prediction engines frequently deploy established rating systems such as Elo, where every completed match dynamically updates a competitor’s estimated strength based on the final result and the rating of the beaten opponent. Surface-adjusted Elo variations prove especially valuable because they isolate general ability from court-specific performance. To calculate the final output, the algorithm might evaluate a player’s projected service performance directly against their opponent’s return capabilities, running parallel computations in reverse before converting the combined signals into a definitive probability.
The underlying algorithmic architectures can vary widely depending on the system’s design. Logistic regression offers an interpretable statistical baseline, tree-based machine learning models can identify complex non-linear interactions between variables, and point-based probability frameworks convert granular serve-point outcomes directly into game, set, and match probabilities. Point-based models possess a distinct mathematical elegance because tennis matches are structurally built from individual points grouped into games and sets. Consequently, even a very slight statistical advantage at the point level can compound into a meaningful edge by the time a match reaches its conclusion.
However, even the most sophisticated point-based frameworks carry inherent limitations. Real-world matches are influenced by shifting tactical patterns, psychological pressure, scorelines, and environmental factors that mathematical models cannot fully capture. A robust prediction system therefore treats point-level simulations as useful components rather than absolute truths.
Reflecting Uncertainty and Embracing Calibration
When all relevant signals are successfully synthesized, a predictive system produces its ultimate output: a projected win probability. These figures are frequently prone to misinterpretation by the public. A 70% win projection does not guarantee that a player will emerge victorious seven times out of ten in a small sample of matches; rather, it signifies that the model estimates roughly a seven-in-ten probability under its specific set of mathematical assumptions. A handful of contrary results on the court do not automatically disprove the validity of the underlying model.
This reality underscores the critical importance of statistical calibration. A predictive model that routinely assigns 70% confidence ratings to outcomes that materialize only 55% of the time is systematically overconfident, regardless of whether its raw percentage of correct winner picks appears impressive at first glance. Conversely, a model with slightly lower raw accuracy can offer far greater utility if its underlying probabilities are meticulously calibrated.
Consequently, public-facing prediction systems should be evaluated over extensive sample sizes across numerous tournaments rather than judged by isolated screenshots or memorable upsets. Metrics such as predictive accuracy, log loss, calibration curves, and out-of-sample testing reveal the true quality of a system. A transparent prediction record becomes infinitely more valuable when every forecast is timestamped, pre-match probabilities are permanently preserved, and actual results are appended objectively without retrospective editing.
One of the definitive hallmarks of a mature, responsibly built prediction model is its capacity to decline to make a definitive call when the available evidence remains weak or contradictory. If a significant ranking gap favors one competitor, yet recent form is entirely mixed, the surface sample size is minimal, and the underlying serve-return matchup remains exceptionally tight, a system that still outputs a soaring confidence score is likely masking uncertainty rather than measuring it accurately.
By deliberately lowering its confidence levels when key signals conflict or when players return from prolonged inactivity with unpredictable schedules, a sensible model prioritizes analytical honesty over forced certainty. Ultimately, no tennis prediction system can eliminate the inherent volatility of elite sport. Injuries, sudden weather shifts, tactical adjustments, nerves, fatigue, and raw variance will forever remain vital components of tennis. The practical purpose of a sophisticated prediction model is not to divine an unknowable future, but to replace vague human impressions with a structured, testable estimate, leaving the ultimate resolution to the players on the court.